unifolm-vla + Unitree G1 (Post 5): deploy inference server, SSH tunnel, and parallel locomotion
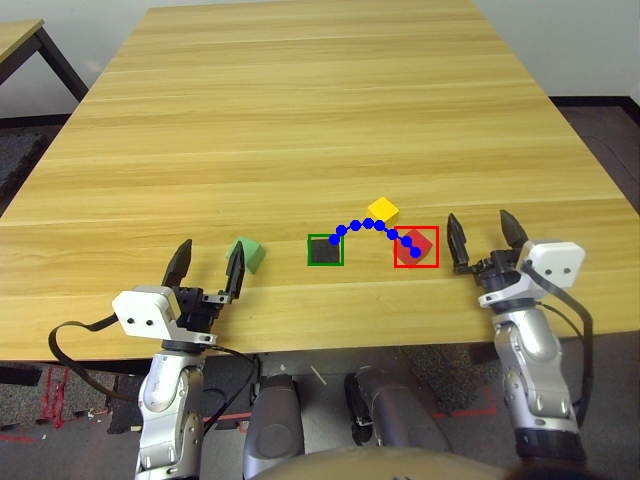
This is the final post of the unifolm-vla + Unitree G1 series. The previous post produced a checkpoint. This post: deploying on a real G1, running inference, and combining parallel locomotion for whole-body behavior.
Before reading: deploying on a real robot always carries risk. Follow the order: sim first → offline test → test with robot in safe mode → full deploy.
Deploy architecture
[Workstation GPU]                [Unitree G1]

  FastAPI Server                  Robot SDK
  run_real_eval_server.py         (arm control)
  port 8777                  ←→   192.168.123.xxx
       ↑
  POST /act
  {image, state, instruction}     (leg control)
       ↓                          unitree_rl_gym
  {action: [28 joints]}           motion.pt
Three parallel processes:
- VLA inference (workstation): receive image → predict action → send to G1
- Arm control (G1): receive joint commands from VLA, execute
- Locomotion (G1): run
motion.ptpolicy independently, controls legs
Step 1: Start the inference server
conda activate unifolm
cd ~/unifolm_ws/unifolm-vla

# With Approach A checkpoint (8-GPU full fine-tune)
python run_real_eval_server.py \
  --ckpt_path /home/user/checkpoints/unifolm_g1_pickplace/best_checkpoint.pt \
  --vlm_pretrained_path /home/user/models/Qwen2.5-VL-7B-Instruct \
  --unnorm_key new_embodiment \
  --host 0.0.0.0 \
  --port 8777 \
  --use_bf16

# With Approach B checkpoint (LoRA single-GPU)
python run_real_eval_server.py \
  --ckpt_path /home/user/checkpoints/lora_g1_pickplace \
  --vlm_pretrained_path /home/user/models/Qwen2.5-VL-7B-Instruct \
  --lora_mode true \
  --unnorm_key new_embodiment \
  --host 0.0.0.0 \
  --port 8777 \
  --use_bf16
Expected terminal output when server is ready:
Loading VLM from: /home/user/models/Qwen2.5-VL-7B-Instruct
Loading checkpoint: /home/user/checkpoints/unifolm_g1_pickplace/best_checkpoint.pt
Model loaded. VRAM usage: 14.3 GB / 24 GB
Starting FastAPI server on 0.0.0.0:8777
INFO:     Application startup complete.
INFO:     Uvicorn running on http://0.0.0.0:8777 (Press CTRL+C to quit)
Verify server is working:
curl -X POST http://localhost:8777/act \
  -H "Content-Type: application/json" \
  -d '{
    "full_image": null,
    "state": [0.0, 0.0, 0.0, 0.0, 0.0, 0.0, 0.0,
               0.0, 0.0, 0.0, 0.0, 0.0, 0.0, 0.0],
    "instruction": "pick up the red cup"
  }'

# Expected response:
# {"action": [0.12, -0.05, 0.33, ...], "timestamp": 1234567890.123}
Step 2: Robot client on G1
G1 has an onboard computer (Jetson Orin NX). The robot client runs there (or on the workstation if connected via LAN).
SSH connection setup
# Test connection to G1 onboard computer
# G1 default IP: 192.168.123.18 (may differ)
ping 192.168.123.18

# SSH into G1 onboard computer
ssh [email protected]
# Default password: "123" or check G1 docs
Robot client script
Create robot_client.py:
"""
Robot client: capture image from G1 camera, send to inference server,
receive action, execute on G1 arm.
"""

import requests
import numpy as np
import time
import base64
import cv2
from unitree_sdk2py.core.channel import ChannelFactory
from unitree_sdk2py.idl.unitree_hg.msg.dds_ import LowCmd_

INFERENCE_SERVER = "http://192.168.1.100:8777"  # workstation IP
TASK_INSTRUCTION = "pick up the red cup"
CONTROL_FREQ_HZ = 5   # ~5Hz, matches VLM inference latency

def encode_image(frame: np.ndarray) -> str:
    _, buffer = cv2.imencode('.jpg', frame, [cv2.IMWRITE_JPEG_QUALITY, 85])
    return base64.b64encode(buffer).decode('utf-8')

def get_joint_states(sdk_interface) -> list:
    state = sdk_interface.get_low_state()
    arm_joints = [state.motor_state[i].q for i in range(13, 27)]
    return arm_joints

def send_action(sdk_interface, actions: list):
    cmd = LowCmd_()
    for i, joint_idx in enumerate(range(13, 27)):   # arm joints only
        if i < len(actions):
            cmd.motor_cmd[joint_idx].q = float(actions[i])
            cmd.motor_cmd[joint_idx].kp = 60.0
            cmd.motor_cmd[joint_idx].kd = 3.0
            cmd.motor_cmd[joint_idx].dq = 0.0
            cmd.motor_cmd[joint_idx].tau = 0.0
    sdk_interface.publish_low_cmd(cmd)

def main():
    ChannelFactory.Instance().Init(0, "eth0")
    cap = cv2.VideoCapture(0)   # left wrist camera

    print(f"Starting robot client. Instruction: '{TASK_INSTRUCTION}'")

    period = 1.0 / CONTROL_FREQ_HZ
    prev_action = [0.0] * 28

    while True:
        t_start = time.time()

        ret, frame = cap.read()
        if not ret:
            continue

        joint_states = get_joint_states(sdk_interface=None)

        payload = {
            "full_image": encode_image(frame),
            "state": joint_states,
            "instruction": TASK_INSTRUCTION,
        }

        try:
            response = requests.post(
                f"{INFERENCE_SERVER}/act",
                json=payload,
                timeout=0.5
            )

            if response.status_code == 200:
                actions = response.json()["action"]

                # EMA smoothing to reduce jerkiness
                alpha = 0.7
                smoothed = [alpha * a + (1 - alpha) * p
                           for a, p in zip(actions, prev_action)]
                send_action(sdk_interface=None, actions=smoothed)
                prev_action = smoothed

        except requests.exceptions.Timeout:
            pass   # keep previous action
        except requests.exceptions.ConnectionError:
            print("Cannot connect to inference server")

        elapsed = time.time() - t_start
        sleep_time = period - elapsed
        if sleep_time > 0:
            time.sleep(sleep_time)

if __name__ == "__main__":
    main()
Run robot client:
python robot_client.py
Step 3: Parallel locomotion with motion.pt
While arm VLA is running, locomotion runs in parallel.
Option A: G1 built-in locomotion (simplest)
G1 has a built-in locomotion controller. Use the Unitree App or remote controller to move the robot while arm VLA handles the arms independently.
# Send stand command via SDK so G1 stays in place during arm tasks
python -c "
from unitree_sdk2py.core.channel import ChannelFactory
from unitree_sdk2py.idl.unitree_hg.msg.dds_ import SportModeCmd_

ChannelFactory.Instance().Init(0, 'eth0')
# send stand mode command...
print('G1 standing — arm VLA running in parallel')
"
Option B: unitree_rl_gym motion.pt
For custom locomotion while arms are working:
conda activate loco
cd ~/unifolm_ws/unitree_rl_gym

# Run pretrained motion policy
python legged_gym/scripts/play.py \
  --task g1 \
  --load_run pretrained \
  --checkpoint motion
Key insight — why they don't conflict:
Arm VLA (robot_client.py):
  → Commands joints 13-26 (arm + gripper)
  → Frequency: ~5Hz

Locomotion (motion.pt):
  → Commands joints 0-11 (legs) + 12 (waist)
  → Frequency: 200-500Hz

Different joint indices → NO conflict.
Safety checklist before running on real G1
BEFORE STARTING:
[ ] E-stop (emergency stop) tested and within reach
[ ] G1 standing on flat floor, no obstacles within 1m
[ ] Joint position limits set in robot_client.py
[ ] Inference server running and verified with curl test
[ ] Camera connected and stable frame rate (>10 FPS)

WHILE RUNNING:
[ ] Keep eyes on G1 at all times
[ ] Second person ready to E-stop if needed
[ ] Log terminal for debugging

STOP WHEN:
[ ] G1 loses balance or joints oscillate
[ ] Joint torque exceeds threshold
[ ] Arm moves unpredictably (policy hallucination)
[ ] Inference server timeout more than 3 times in a row
Troubleshooting
Server not receiving images (full_image: null)
# Test camera capture separately
import cv2
cap = cv2.VideoCapture(0)
ret, frame = cap.read()
print("Camera OK:", ret, "Frame shape:", frame.shape if ret else None)
Arm moves jerkily
Cause: inconsistent inference latency
Fix: EMA smoothing is already in the client above (alpha=0.7)
     If still jerky, reduce alpha to 0.5 (smoother, slightly less responsive)
Policy doesn't perform the task correctly
Debug checklist in order:
1. Is lighting the same as during training? (different lights = distribution shift)
2. Is object at the right position? (shifted too far = out-of-distribution)
3. Is camera still calibrated correctly? (wrist camera shifted?)
4. Is instruction text identical to training instructions?
5. Is this the best checkpoint? (use the one with lowest val loss)
G1 arm resets to home position after a few seconds
Cause: G1 SDK has a safety timeout — if no command received within N seconds,
       arm returns to home position
Fix: ensure robot_client.py sends commands continuously even when holding still
     (send action = previous_action if timeout)
Full series summary
After 5 posts, you have a complete pipeline:
| Post | Input | Output | Tools |
|---|---|---|---|
| 1: Architecture | — | Understanding the system | 3 repos |
| 2: Data collection | G1 + Meta Quest 3 | 50+ JSON demos | xr_teleoperate |
| 3: Data pipeline | JSON demos | RLDS dataset | unitree_IL_lerobot + unifolm-vla |
| 4: Fine-tune | RLDS dataset | VLA checkpoint | DeepSpeed / LoRA |
| 5: Deploy (this post) | Checkpoint + G1 | Robot performs task | FastAPI + Unitree SDK |
Next steps to improve:
- More data diversity: 200+ demos with lighting variation and varied object positions
- Multi-task: collect data for multiple tasks, train a single model on all of them
- Deeper locomotion integration: train a policy that walks to objects before picking up
- When Unifolm-VLM-0 becomes public: fine-tune from that checkpoint → ~15-20% better performance