Series
Robot 3d Manipulation Vla
Series "Robot 3d Manipulation Vla" gồm 7 phần, đọc theo thứ tự từ phần 1.
Research & Trends
Vì sao VLA 2D chưa đủ cho manipulation
VLA dùng ảnh RGB 2D đang chạm trần: depth ambiguity, occlusion, thiếu metric scale. Bài mở đầu series: vì sao 3D là hướng đi tất yếu, từ DP3 đến WholeBodyVLA.

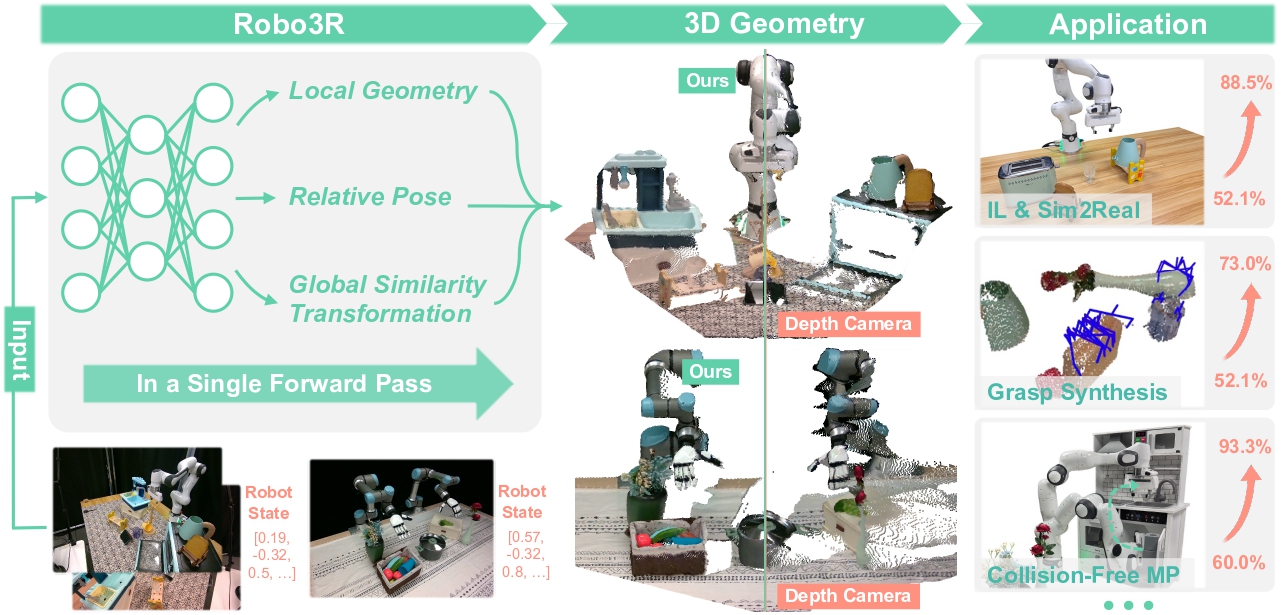
Robo3R: tái dựng 3D feed-forward cho robot arm
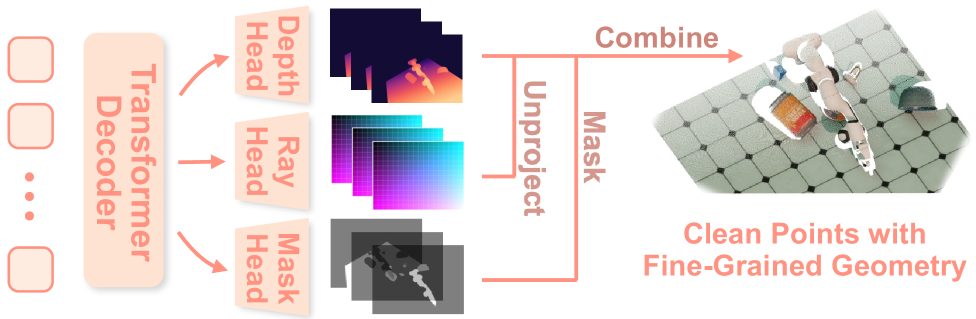
Từ camera RGB và trạng thái robot, Robo3R dựng hình học 3D metric-scale thời gian thực — không cần depth sensor, không cần SLAM, 43 Hz single view.

DP3: 3D Diffusion Policy với point cloud (hands-on)
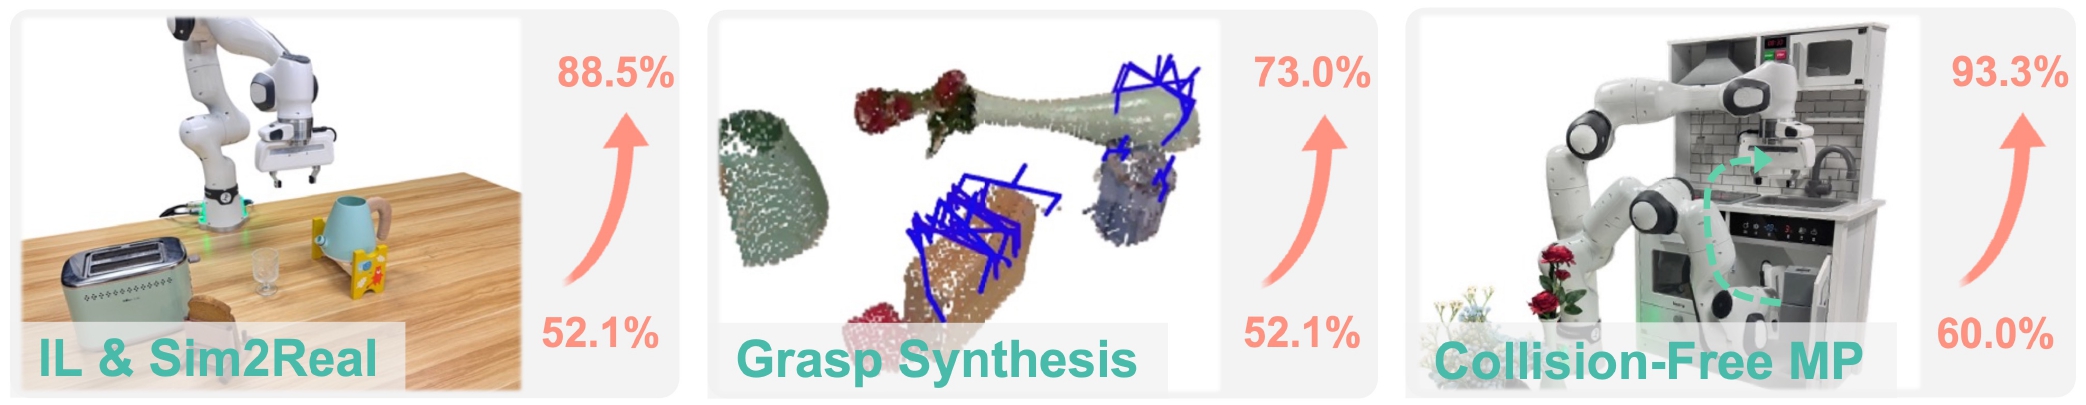
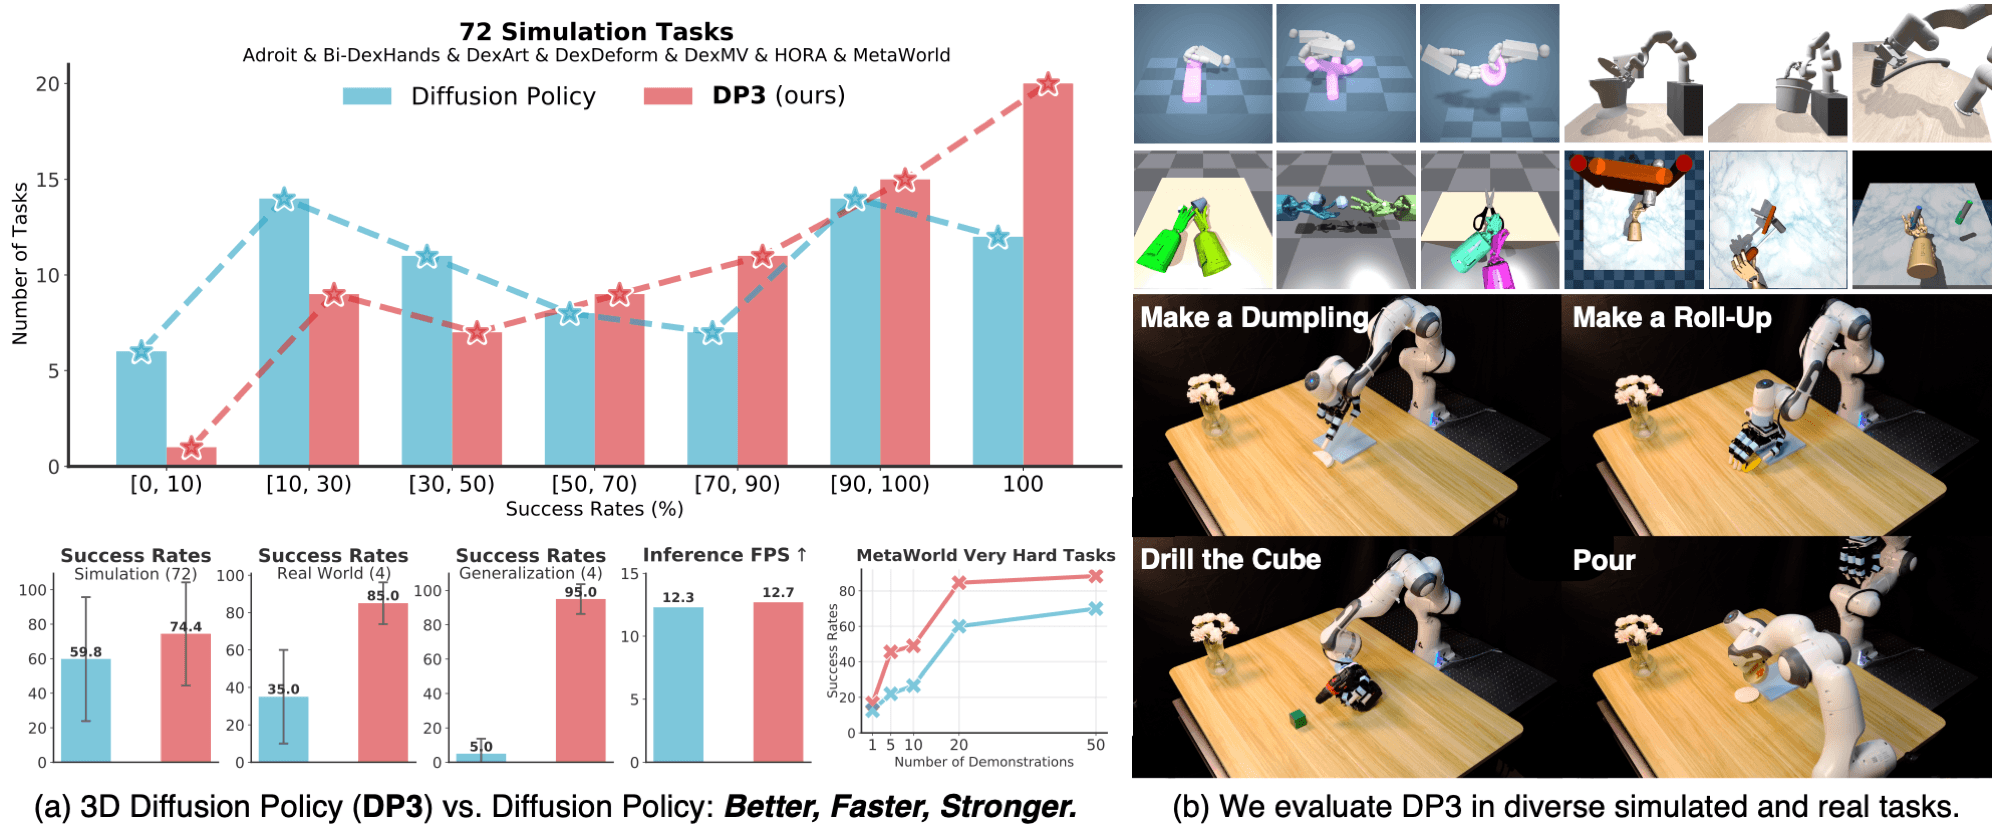
DP3 biến point cloud thành input cho diffusion policy — 24.2% cải thiện trên 72 tasks, 85% success rate robot thật. Hands-on: cài đặt, train, eval từ repo gốc.

Perception 3D cho humanoid: Omni-Manip & spatial reasoning
Humanoid vừa đi vừa với tay xa cần perception ngoài FOV camera. Phân tích Omni-Manip và Active Spatial Reasoning — 2 paper humanoid 2026.

WholeBodyVLA: video egocentric + RL loco-manipulation
WholeBodyVLA học từ video egocentric action-free, nối VLA cấp cao với RL cấp thấp cho whole-body loco-manipulation. Paper ICLR 2026, test trên AgiBot X2.

Thu data manipulation: teleop vs robot-free vs video
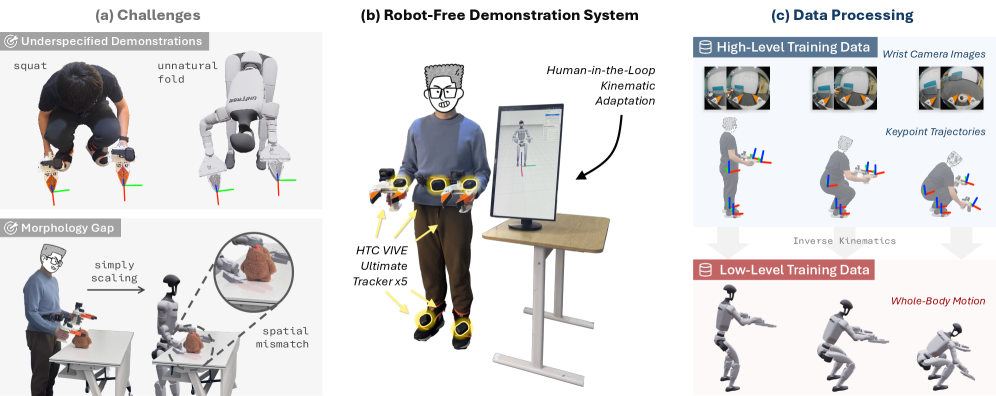
Ba chiến lược thu dữ liệu whole-body manipulation: teleop, robot-free demo (HuMI), video egocentric action-free — so sánh cost/quality/throughput.

Roadmap 3D manipulation cho humanoid Unitree G1
Bài capstone: ghép Robo3R, DP3, Omni-Manip và WholeBodyVLA thành pipeline cho Unitree G1 — bố trí cảm biến, chọn policy, chọn data, checklist sim2real.